Top 20 Statistical Methods You Should Know
By William DavisFebruary 16, 2026
Statistics isn't just for mathematicians and data scientists anymore. Whether you're analyzing business data, conducting research, or trying to make sense of trends, knowing the right statistical methods can change how you understand information.
Let's cut through the complexity and look at 20 statistical methods that actually matter. You don't need a PhD to use these. You just need to know when and how to apply them.
Definitions and formulas below are checked against the NIST/SEMATECH e-Handbook of Statistical Methods, a public engineering statistics reference maintained by the U.S. National Institute of Standards and Technology.
Why Statistical Methods Matter
Every day, you make decisions based on data. Should you launch that new product? Is your marketing campaign working? Are customer complaints increasing or just seeming worse?
Without the right statistical tools, you're guessing. With them, you're making informed choices backed by evidence. The methods we'll cover range from simple to advanced, but each one solves real problems that people face in work and research.
Descriptive Statistics: Understanding Your Data
1Mean, Median, and Mode
These three measures tell you what's typical in your data, but they each tell a different story.
The mean is your average. Add up all values and divide by how many you have. It works great until outliers mess it up. If nine people earn $50,000 and one earns $5 million, the mean salary is $545,000. That's not typical at all.
The median is the middle value when you line everything up. It handles outliers better. In our salary example, the median stays at $50,000.
The mode is whatever shows up most often. It's perfect for categorical data like "What's the most popular product color?"
When to use each:
- Mean: normal distributions without outliers
- Median: data with outliers or skewed distributions
- Mode: categorical data and finding most common values
2Standard Deviation and Variance
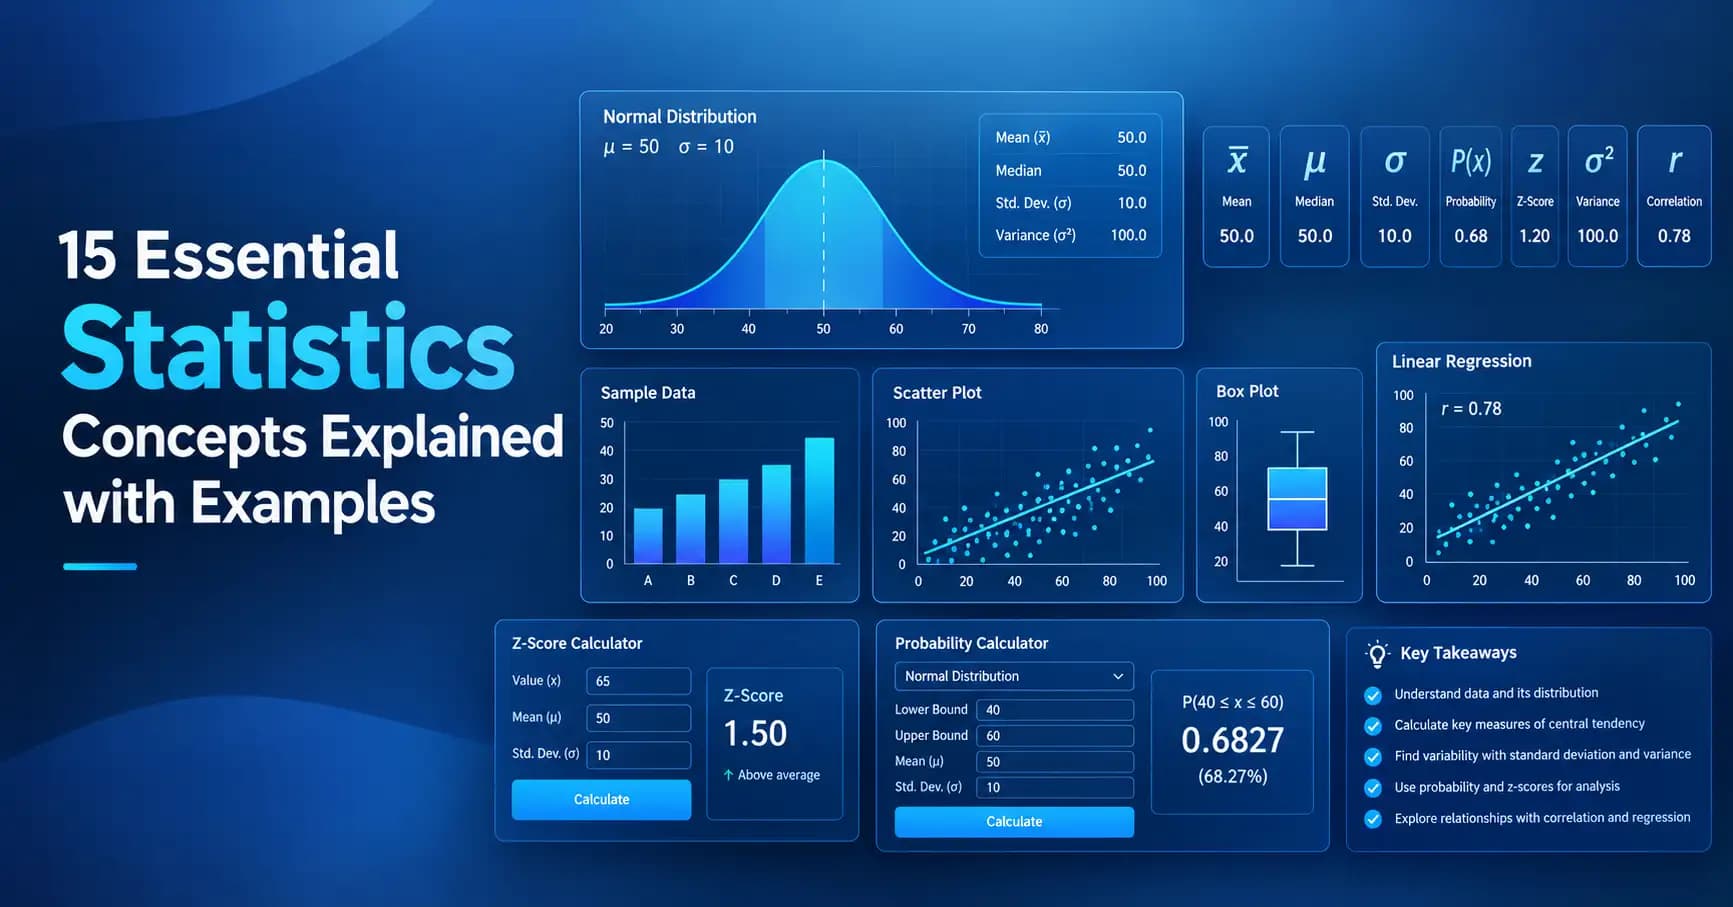
Standard deviation tells you how spread out your data is. Low standard deviation means values cluster tightly around the mean. High standard deviation means they're all over the place.
Variance is just standard deviation squared. It's useful in calculations but harder to interpret because it's not in the same units as your original data.
Why does this matter? If you're manufacturing parts, low standard deviation means consistent quality. If you're looking at test scores, high standard deviation means students performed very differently from each other.
3Percentiles and Quartiles
Percentiles split your data into 100 equal parts. If you scored in the 90th percentile, you did better than 90% of people.
Quartiles divide data into four parts. The first quartile (Q1) is the 25th percentile, the second (Q2) is the median, and the third (Q3) is the 75th percentile.
The interquartile range (IQR) between Q1 and Q3 shows where the middle 50% of your data lives. It's great for spotting outliers.
Testing Relationships and Differences
4T-Test
T-tests compare averages between groups to see if differences are real or just random chance.
Use a one-sample t-test to compare your sample mean against a known value. Use an independent samples t-test to compare two different groups. Use a paired t-test when you're measuring the same subjects twice.
For example, did the new training program improve employee performance? Compare test scores before and after with a paired t-test.
5Z-Test
Z-tests are like t-tests but work better with large samples (usually over 30). They also require you to know the population standard deviation, which you often don't have in real research.
Use z-tests for quality control in manufacturing where you know historical standards. They're faster to calculate and just as reliable as t-tests when sample sizes are big enough.
6ANOVA (Analysis of Variance)
ANOVA compares means across three or more groups at once. Running multiple t-tests increases your chance of false positives, but ANOVA keeps that risk controlled.
One-way ANOVA has one independent variable (like comparing productivity across three shifts). Two-way ANOVA has two (like comparing productivity across shifts AND departments).
ANOVA tells you if groups differ, but not which groups. That's where post-hoc tests come in.
7Chi-Square Test
Chi-square tests work with categorical data. Did more people click the red button or the blue button? Is there a relationship between education level and voting preference?
The chi-square test for independence checks if two categorical variables are related. The goodness-of-fit test checks if your observed data matches an expected distribution.
You need at least five expected observations per category for the test to work reliably.
Measuring Relationships
8Correlation (Pearson, Spearman, Kendall)
Correlation measures how two variables move together. Pearson correlation works with continuous data and linear relationships. Values range from -1 (perfect negative correlation) to +1 (perfect positive correlation).
Spearman and Kendall correlations handle ranked data and non-linear relationships better.
Remember: correlation doesn't mean causation
Ice cream sales and drowning deaths correlate, but ice cream doesn't cause drowning. They're both caused by hot weather.
9Linear Regression
Regression lets you predict one variable based on others. Simple linear regression uses one predictor. Multiple regression uses several.
The equation is straightforward: Y = a + bX. You're finding the line that best fits your data points.
Use it to predict sales based on advertising spend, estimate house prices based on square footage, or forecast anything where you have historical data showing a relationship.
10Logistic Regression
When your outcome is yes/no, pass/fail, or any binary result, you need logistic regression instead of linear.
Will a customer buy or not? Will a patient develop a disease or not? Logistic regression gives you probabilities, not just straight predictions.
It's one of the most used methods in machine learning and medical research.
Non-Parametric Methods
11Mann-Whitney U Test
This is the non-parametric alternative to the independent samples t-test. Use it when your data doesn't follow a normal distribution or when you're working with ranked data.
It compares the medians of two groups instead of means. You're testing if one group tends to have higher values than the other.
Perfect for survey data using Likert scales or any situation where you can rank responses but not measure exact differences.
12Wilcoxon Signed-Rank Test
This replaces the paired t-test when your data isn't normally distributed. It looks at the differences between paired observations and tests if those differences center around zero.
Use it for before-and-after studies where you can't assume normality.
13Kruskal-Wallis Test
Think of this as non-parametric ANOVA. It compares three or more groups using ranks instead of means.
When your data is heavily skewed or you're working with ordinal data, Kruskal-Wallis is your friend.
Time Series and Forecasting
14Moving Averages
Moving averages smooth out short-term fluctuations to reveal longer-term trends. A 7-day moving average takes the average of the last seven days, then moves forward one day and calculates again.
Simple moving averages weight all points equally. Weighted moving averages give more importance to recent data.
Stock traders use these constantly. Businesses use them to forecast demand and plan inventory.
15Exponential Smoothing
Exponential smoothing gives exponentially decreasing weights to older observations. Recent data matters more, which makes sense for most forecasting.
It's simpler than ARIMA models but often just as accurate for short-term predictions.
16ARIMA Models
ARIMA (AutoRegressive Integrated Moving Average) models are the heavy hitters of time series forecasting. They account for trends, seasonality, and autocorrelation.
They're complex to set up but powerful once configured properly. Use them for sales forecasting, economic indicators, or any data with strong time-based patterns.
Advanced Methods
17Principal Component Analysis (PCA)
PCA reduces the number of variables in your dataset while keeping most of the information. If you have 50 variables, PCA might let you capture 90% of the variation with just five principal components.
It's useful for data visualization, noise reduction, and as a preprocessing step for machine learning.
18Cluster Analysis
Cluster analysis groups similar observations together without predefined categories. K-means clustering is the most common approach.
Use it for customer segmentation, identifying patterns in behavior, or grouping similar items in any dataset.
Netflix uses clustering to group users with similar viewing habits. Retailers use it to identify customer types.
19Factor Analysis
Factor analysis identifies underlying variables (factors) that explain patterns in your data. It's like PCA but focuses on finding hidden causes rather than just reducing dimensions.
Psychologists use it to identify personality traits from survey responses. Marketers use it to understand what drives consumer behavior.
20Survival Analysis
Survival analysis (also called time-to-event analysis) studies how long until something happens. How long until a machine fails? How long do customers stay subscribed?
The Kaplan-Meier estimator and Cox proportional hazards model are the main techniques. They handle censored data, where you don't observe the event for everyone in your study.
Medical research relies heavily on survival analysis for studying disease progression and treatment effectiveness.
Choosing the Right Method
Picking the right statistical method depends on three things: your data type, your question, and your assumptions.
Data Type
Continuous data (measurements like height, weight, time) works with different methods than categorical data (groups like color, brand, yes/no).
Your Question
Are you comparing groups, looking for relationships, or trying to predict? Each goal points you toward different methods.
Assumptions
Check your assumptions. Do you have a normal distribution? Is your sample large enough? Are observations independent?
Common Mistakes to Avoid
Don't use parametric tests when your data violates assumptions
The results will be unreliable.
Don't confuse statistical significance with practical importance
A tiny difference can be statistically significant with a huge sample but meaningless in practice.
Don't forget about sample size
Small samples lack power. You might miss real effects because you don't have enough data.
Don't p-hack
Trying multiple tests until you get a significant result is how you fool yourself.
Putting It All Together
You don't need to master all 20 methods tomorrow. Start with the basics: descriptive statistics, t-tests, and correlation. Learn what your data looks like before you test anything.
As you encounter new problems, add new methods to your toolkit. Most statistical software makes running these tests easy. The hard part is knowing which test to use and how to interpret the results.
Key Takeaway:
Statistics helps you see past randomness to find real patterns. It turns guesses into evidence-based decisions. Whether you're in business, research, healthcare, or just trying to make sense of data, these 20 methods give you the tools to do it right.